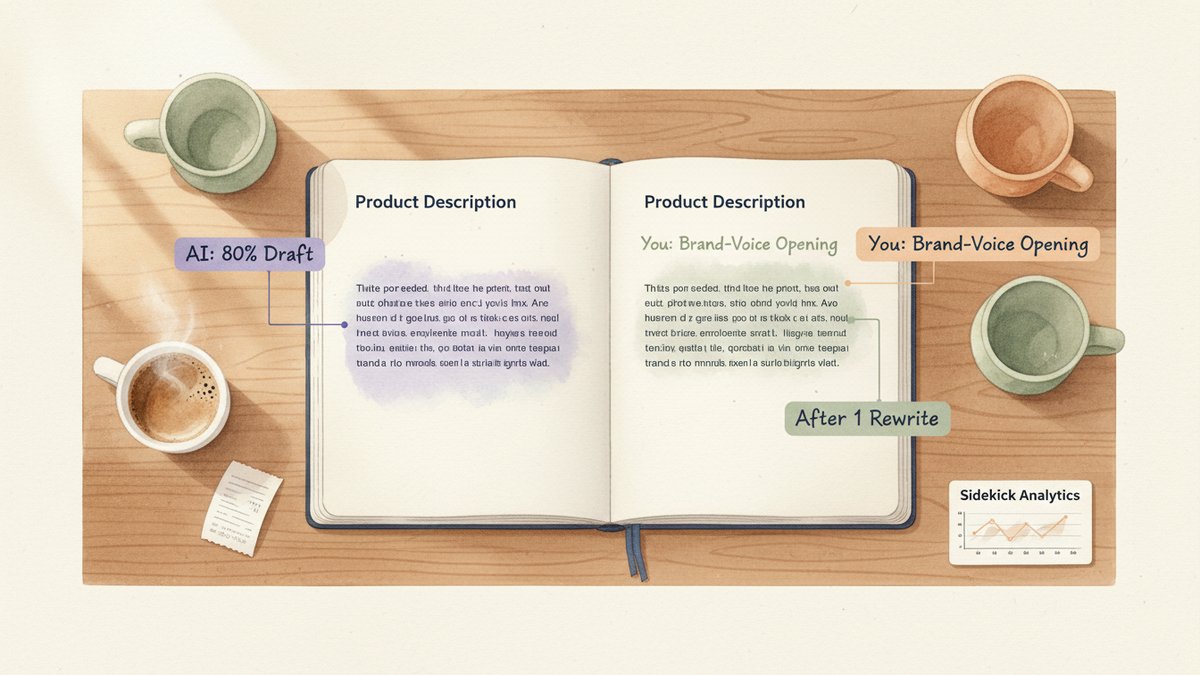
A 50-SKU store owner's 90-day production test of Shopify Magic and Sidekick — what saved hours, what hallucinated, and the 80/20 truth about AI writing your product pages.
A practical walkthrough of Synthesia for marketers — what it's actually good at, who should pay for it, the real 8-step workflow, 2026 pricing, and the limits nobody mentions until you hit them.
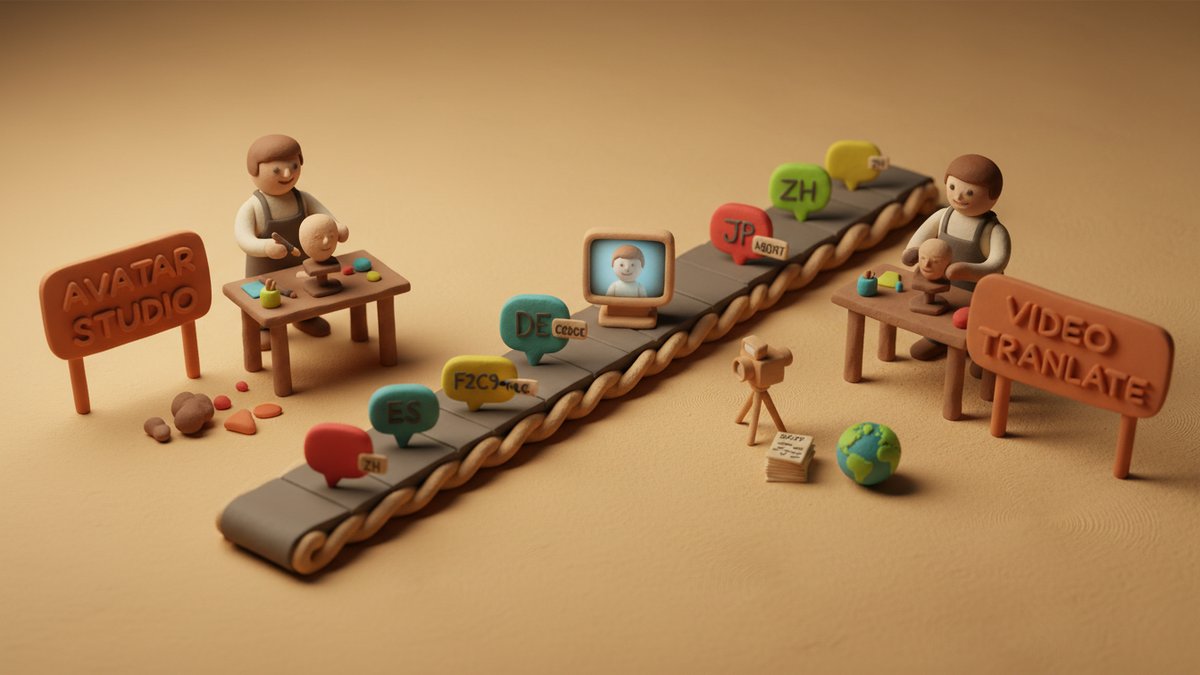
What HeyGen actually does, who it is for, and how to use it — a practical walk-through of Instant Avatar, Photo Avatar, 175-language Video Translate, pricing tiers, and the trade-offs vs. Synthesia for marketers running multilingual campaigns.
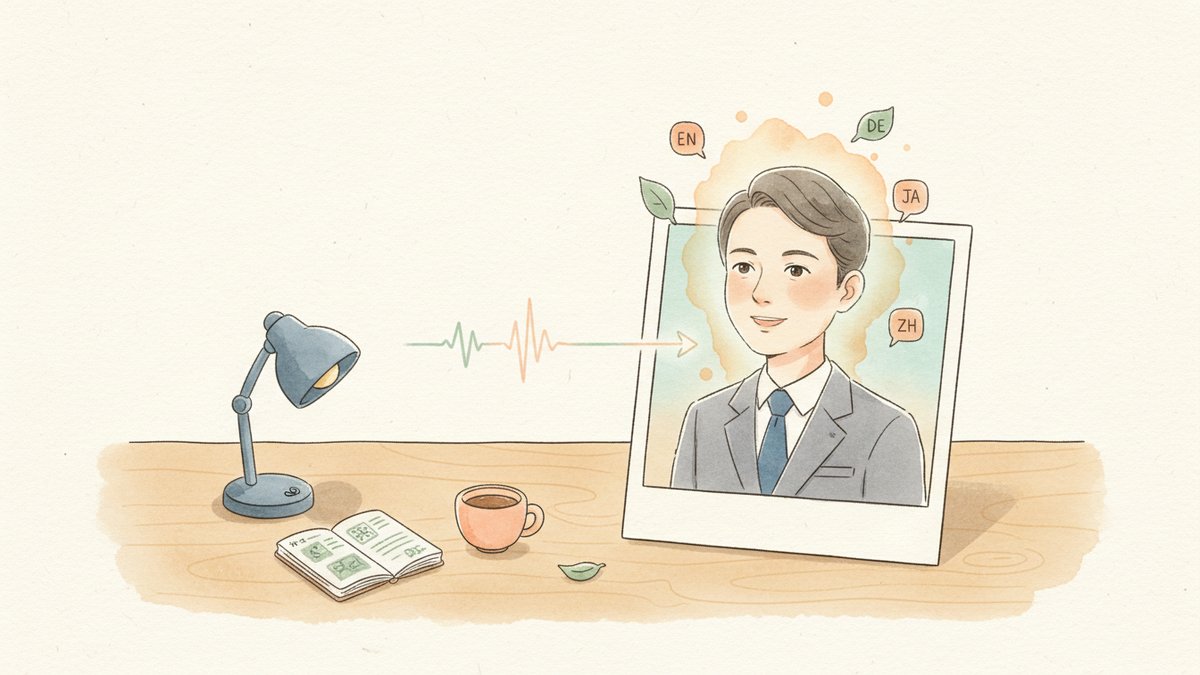
D-ID's 'Creative Reality' turns a single photo into a talking avatar in minutes. Here's the real workflow, current pricing, and when to pick it over HeyGen or Synthesia.
I built a B2B SaaS webinar landing page with Wix Harmony and the full Wix AI suite in under 30 minutes. Here is the build journal — what the AI produced out of the box, what I had to rewrite, and whether the speed gain is real or a hidden tax on conversion.
Two client sites, three months, one rebranded AI builder. Where Blueprint AI Design Intelligence actually helps a designer — and where it defaults to the same template every other Squarespace site ships with.
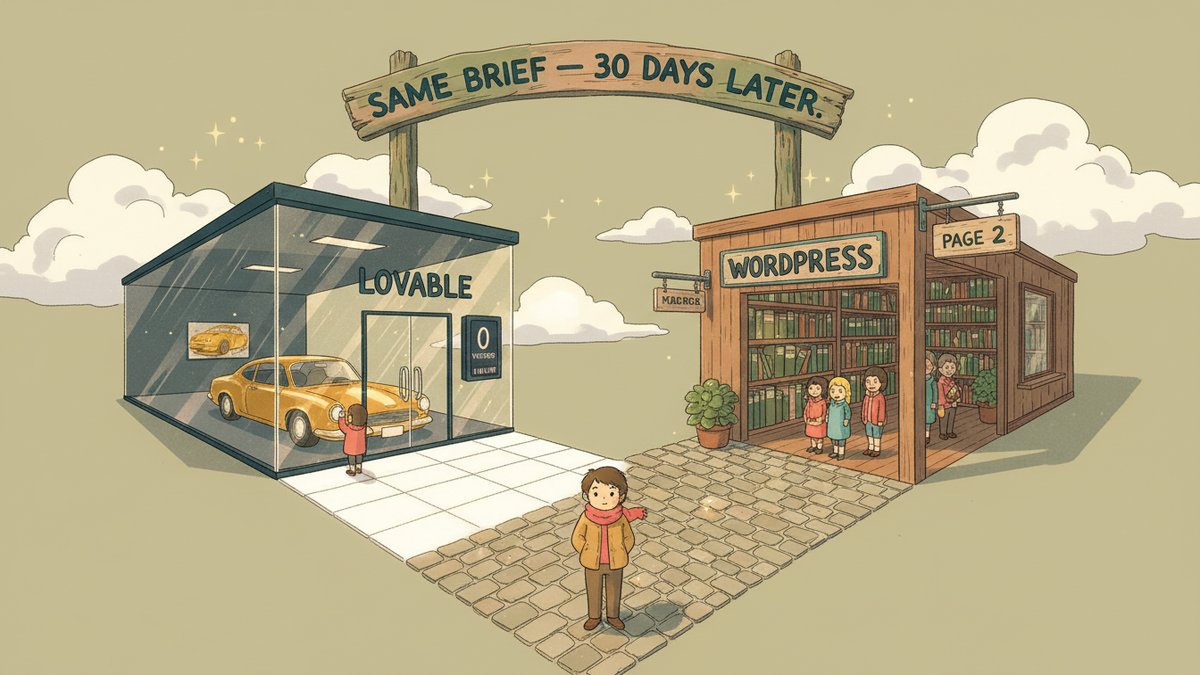
Two real builds, one head-to-head: the same B2B SaaS lead-gen site, built first on Lovable (1 day, 6 credits, gorgeous) and then on WordPress (5 days, ranked page 2 in 30 days). What I'd pick for what, and why the SEO content flywheel is WordPress's real moat.
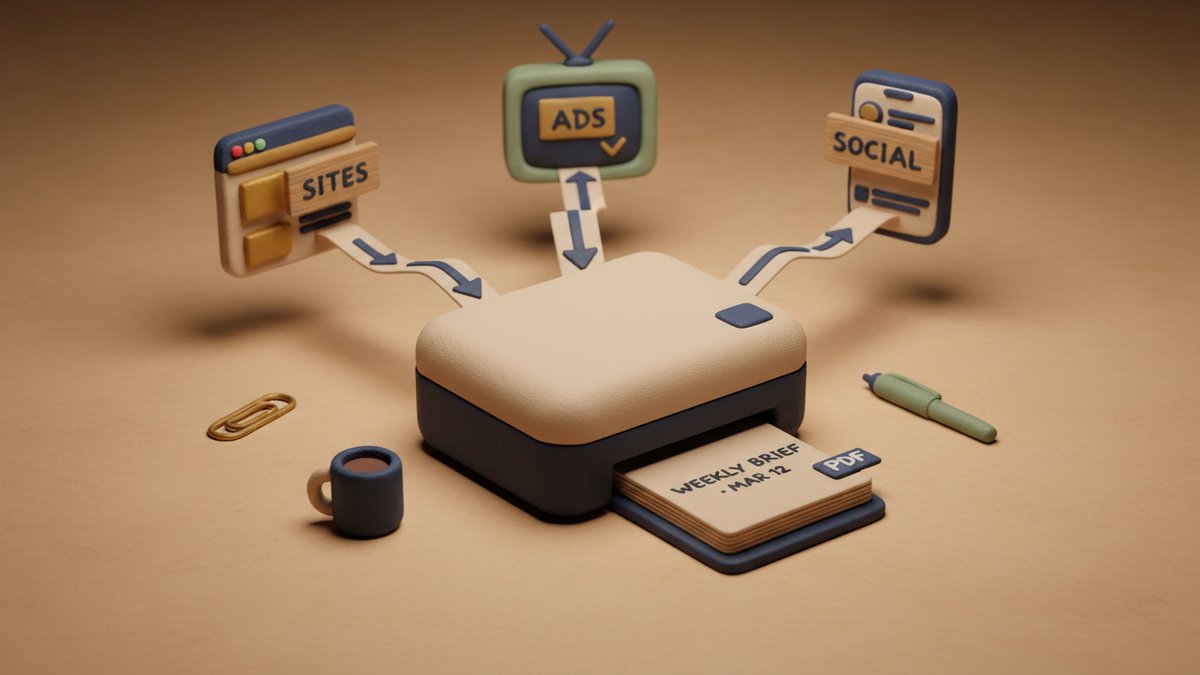
A 3-sub-agent competitive intel pipeline that produces an 8-page PDF brief every Friday at 6am — no human reads a single competitor page in between. The parent Claude agent dispatches a site-watcher, an ad-watcher, and a social-watcher, each returns a strict JSON schema, the parent synthesizes everything into a Markdown brief that Pandoc renders to PDF. The parent prompt, the three JSON contracts, the PDF template, and the failure modes that have actually cost me a brief.
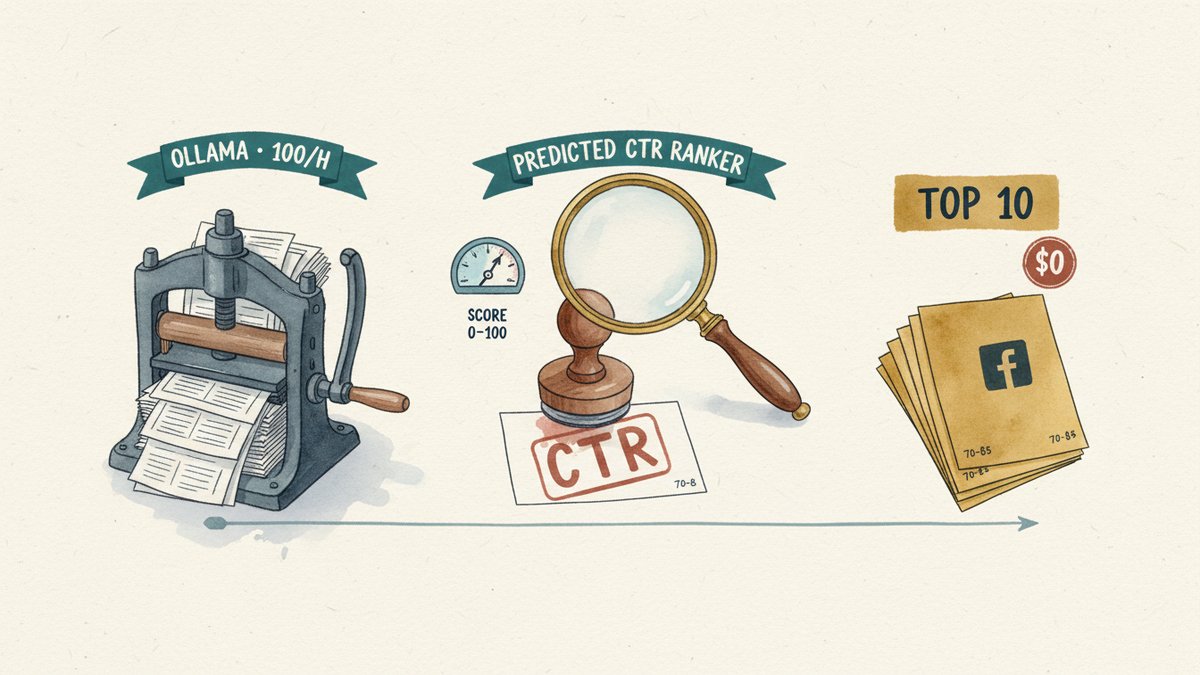
Generate 100 paid-social ad variants per hour on a local M-series Mac via Ollama + Llama 3.3 70B, then run a second pass that scores each variant 0-100 on hook, value clarity, and CTA specificity. The full prompt pair, the Python wrapper, and the math that makes $0 marginal cost win over GPT-4o at any team size.
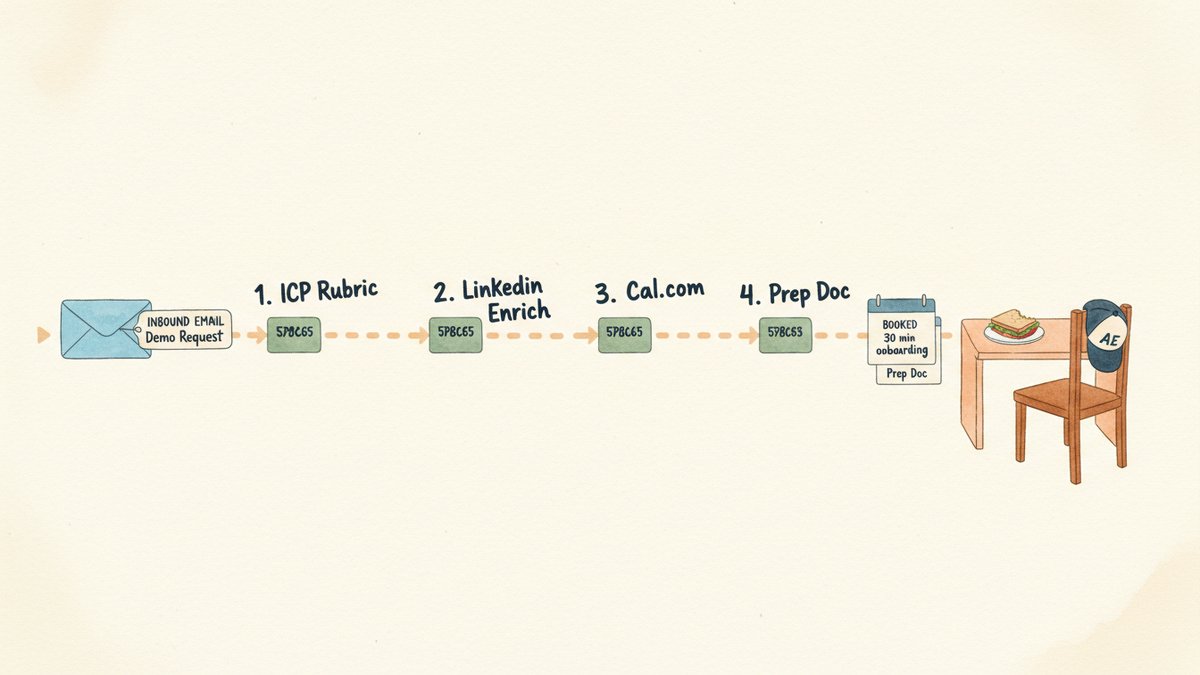
A production pipeline that takes a 'demo request' email, qualifies it against an ICP rubric, enriches from LinkedIn, books a Cal.com slot in the prospect's timezone, and sends a personalized prep doc 24h before the call — all before a human touches the lead. The full Make scenario, the actual Operator instruction set, the ICP rubric, the prep doc prompt, and the three failure modes that have actually cost me time. ⚠️ Operator UI may shift; the framework stays.
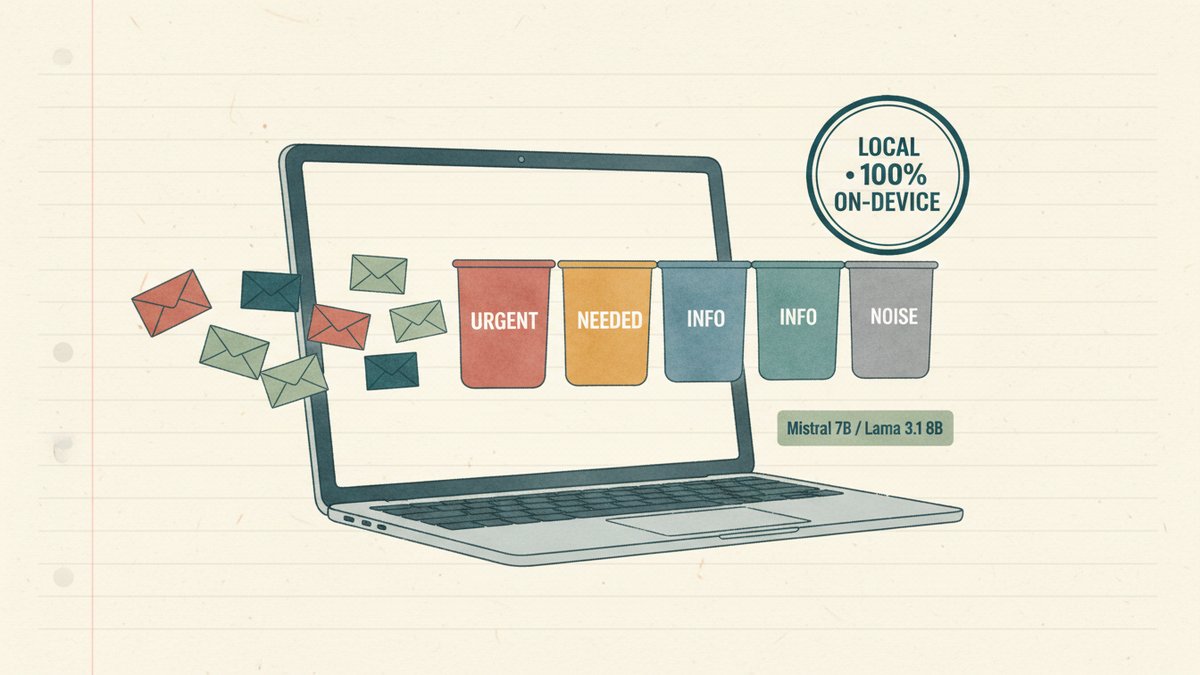
A 6-week, 8,400-email field test of running a privacy-respecting local-LLM email triage layer on Apple Silicon — Apple Mail → AppleScript → Ollama-served Mistral 7B or Llama 3.1 8B — with a 4-bucket rubric, real hardware benchmarks, and a 92% accuracy figure you can reproduce.
A 30-day blind test: 800 meta titles + 800 product descriptions rewritten by both Qwen 2.5 14B (self-hosted on a refurbished workstation) and Claude Sonnet 4, rated by 3 SEO contractors. The result is not a clean win for open weights — it's a split. Where Qwen breaks even, where it collapses, and the actual cost math behind self-hosting for repeat-pattern SEO work.